
Own the intelligence.
Grafion Labs is engineering dedicated personal AI computers to run frontier autonomous software agents continuously — with zero recurring cloud subscriptions, zero rate limits, and complete data sovereignty.
Engineered to surpass cloud frontier models on complex multi-file application development and verification loops.
Overcoming the memory bandwidth wall with tiered memory hierarchies and adaptive MoE expert locality caching.
A computer you physically own. Zero cloud API calls, zero telemetry, and permanent offline capability.
Quiet, desktop-class thermals built for around-the-clock research, code generation, testing, and deployment.
Engineered for Continuous Local Intelligence
Grafion Labs integrates physical hardware, sparse model architecture, and high-bandwidth memory hierarchies into a cohesive ecosystem for personal AI autonomy.
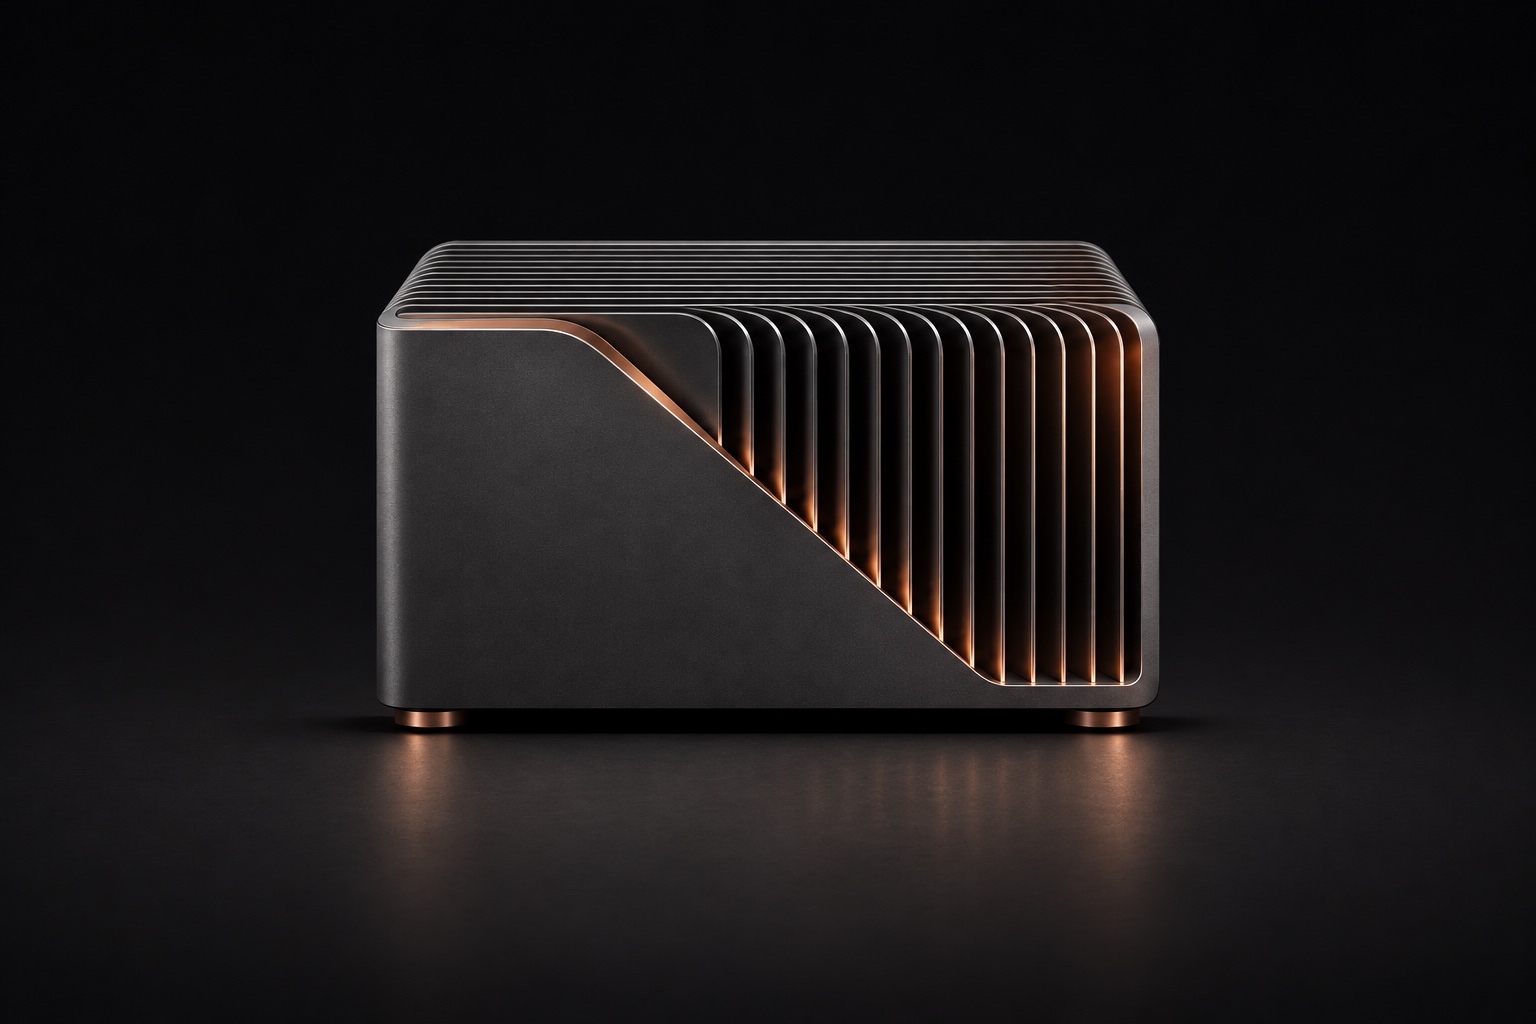
PRAXON
An engineered desktop appliance purpose-built to execute autonomous AI engineering agents locally. Designed to live in your physical workspace, operating continuously without cloud inference fees or network telemetry.
MORPHE
A specialized reasoning and code generation model designed to surpass Claude Opus in autonomous multi-file application development, system architecture, interactive debugging, and verified test execution.
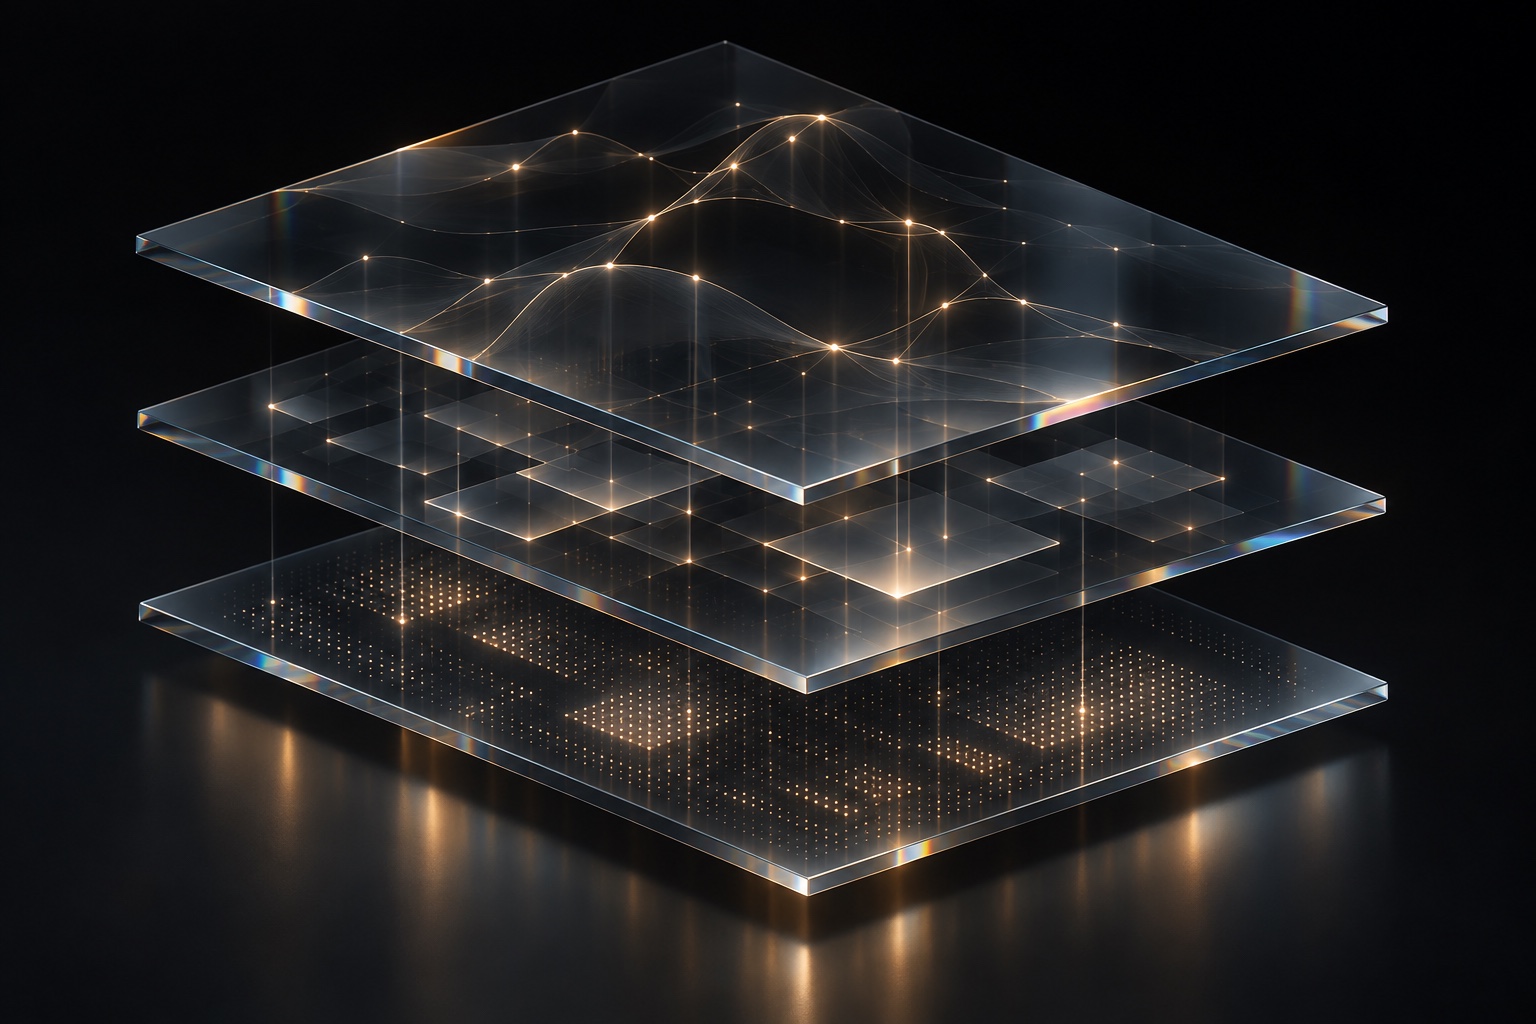
PRAXION
The co-designed inference runtime bypassing the physical memory bandwidth bottleneck through high-speed accelerator RAM, dynamic MoE expert locality caching, and fast system memory pipelines.
A Unified Approach to Personal Frontier AI
Running frontier-grade autonomous intelligence locally cannot be achieved through software optimization or commodity hardware alone. Grafion Compute harmonizes model architecture, runtime physics, and manufacturing economics.
Frontier Autonomous Intelligence
Developing specialized coding models and agent workloops capable of complex full-stack software development, architectural reasoning, and self-correcting test-driven execution.
Co-Designed Hardware & Efficiency
Overcoming the fundamental memory bandwidth bottleneck through tiered memory architectures, adaptive expert caching, and task-specific quantization.
Precision Manufacturing & EU Distribution
Structuring a reliable global contract assembly network to build accessible, enterprise-grade AI workstations compliant with all European regulatory standards.
Solving the Memory & Inference Physics
Running frontier intelligence locally is fundamentally an engineering challenge of memory bandwidth, thermal dissipation, and hardware cost. Here is how Grafion Compute addresses the challenge.
The Memory Bandwidth Wall
Large-scale autoregressive models require loading active parameter weights for every generated token. Frontier intelligence at interactive speeds requires hundreds of gigabytes per second of sustained throughput.
Sparse Mixture-of-Experts Locality
MoE models activate only a small fraction of their total parameters per token. In software development tasks, expert activations exhibit strong temporal and domain locality.
Tiered Memory Hierarchy
Rather than relying solely on prohibitively expensive HBM, our architecture evaluates hybrid configurations combining ultra-fast accelerator RAM, high-capacity system memory, and high-speed NVMe.
Task-Aware Precision Optimization
Software engineering requires exact syntax, logical coherence, and long-range symbol tracking. Uniform extreme quantization often degrades multi-file reasoning capabilities.
The 7-Stage Evidence Ladder
The AI hardware industry is plagued by speculative marketing and decorative progress bars. Grafion Compute operates on a strict verification hierarchy where targets are never conflated with verified achievements.
Register for Research & Developer Updates
We are not accepting pre-orders or taking customer payments. Join our private notification list to receive peer-reviewed research updates, benchmark telemetry, and early prototype trial invitations.